
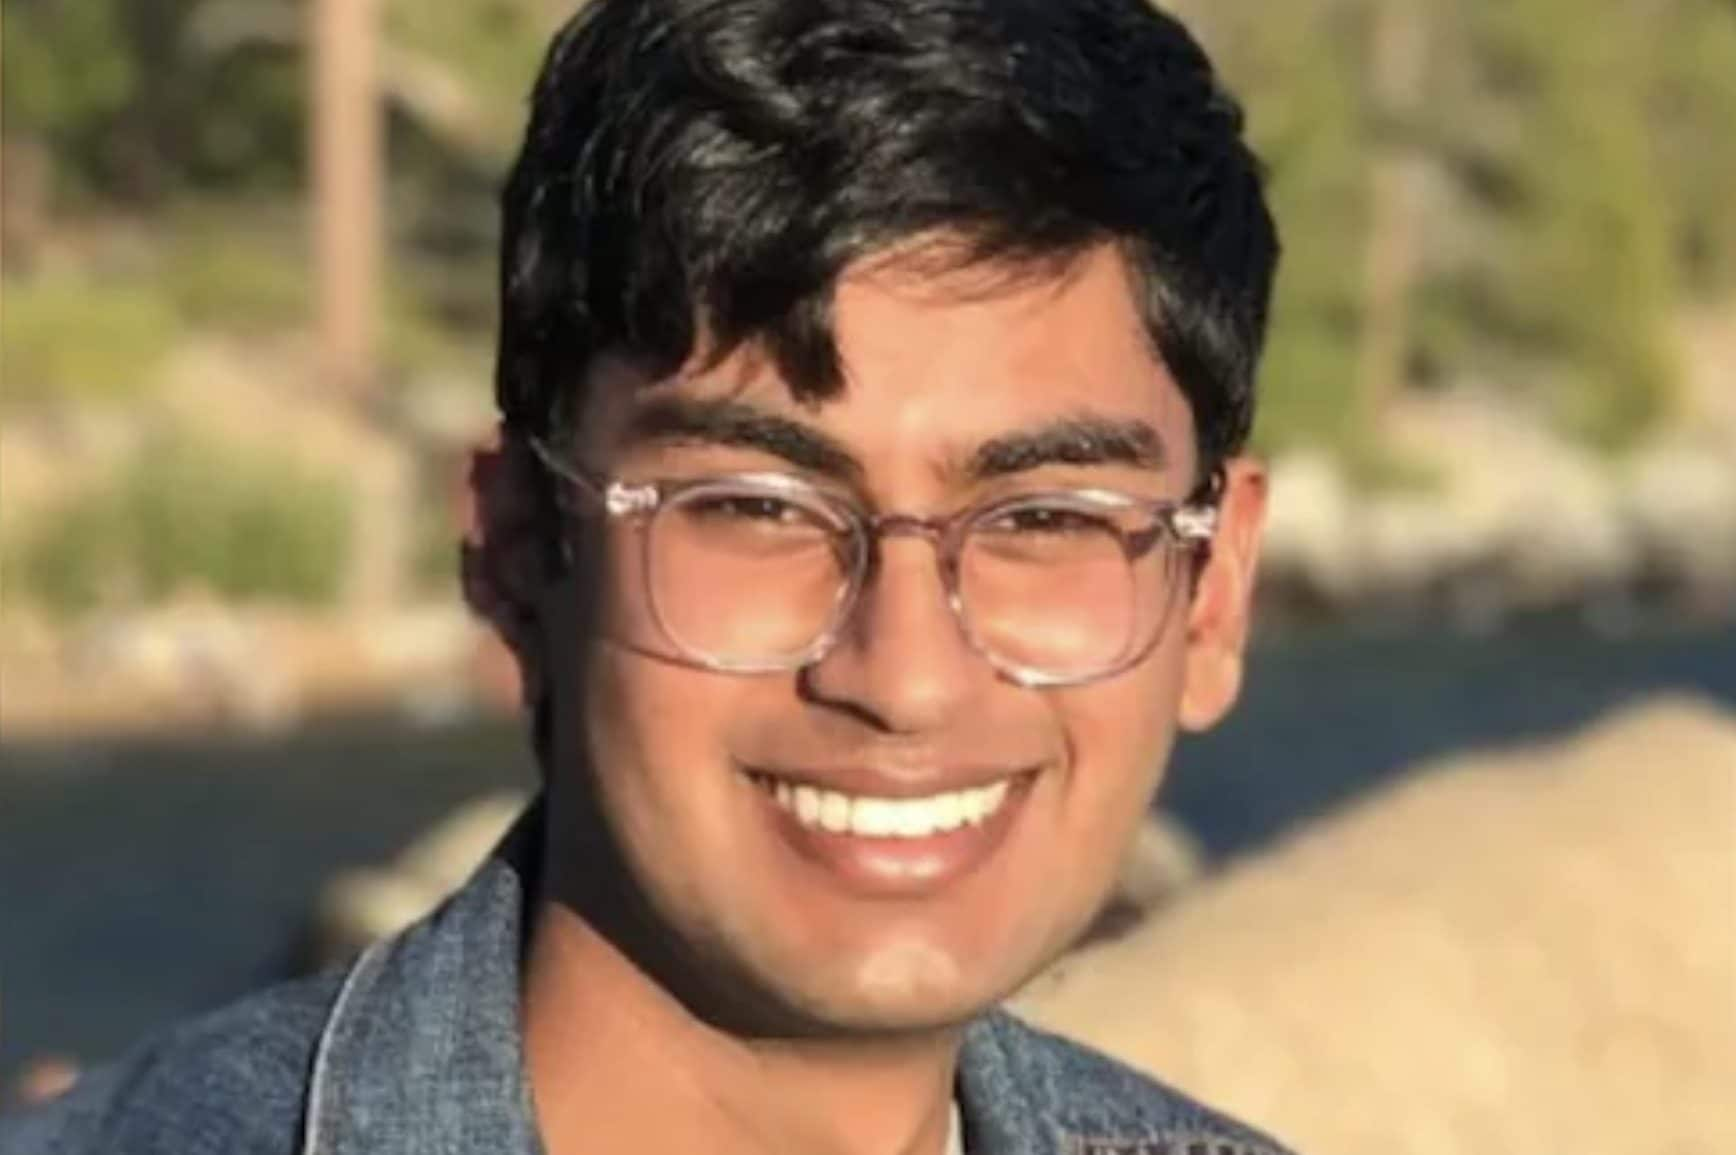
Suchir Balaji worked for four years at OpenAI, the company that developed ChatGPT. Computer expert, he worked in the technical staff. In August 2024 he made a series of statements to the New York Times accusing OpenAI of using copyrighted data to train its artificial intelligence models.
Suchir Balaji, 26, worked for until last August OpenAIthe artificial intelligence company that created ChatGPT. He worked here for four years after his studies in computer science at the University of California. As can be seen from his LikedIn profile he was a member of the technical staff, specializing in machine learning. His was no ordinary farewell to the company. When he decided to leave, he gave an interview to the New York Times in which he accused OpenAI of having built its artificial intelligence models with data protected by copyright.
In the last few hours the San Francisco authorities have revealed that Suchir was found dead. The death was discovered on November 26 but silence has been maintained until now. The body was in an apartment and initial information seems to confirm that it was a suicide. The officers intervened after a phone call asking to check on the boy’s health condition. There confirmation of suicide it also came from the medical examiner who is following the case.
Suchir Balaji’s accusations against OpenAI
According to Suchir Balaji, OpenAI’s problem is all in the first place data chosen by the company to train its models of artificial intelligence, specifically ChatGPT. It’s a topic that has been widely discussed since the fall of 2023, when the era of chatbots began. The question is simple: what data did ChatGPT use to learn to respond so well?
With AI, weather forecasts will be reliable even for 15 days: how Google’s model works
For Balaji it was about copyrighted data: “OpenAI’s use of copyrighted data to create ChatGPT violated the law.” And again: “This is not a sustainable model for the Internet ecosystem as a whole.” On this front the ongoing lawsuits against OpenAI there are several, starting from the one started in December 2023 by New York Times.
At the moment the company has always defended itself by saying that it had only used freely accessible information by anyone. Despite this, in the last year OpenAI has also been joined by other causes, organized by publishing houses or groups of authors from whom texts and publications were allegedly stolen. Not only that, a group of programmers also sued OpenAI and Microsoft on charges of training CoPilot’s artificial intelligence using pieces of open source software. At the moment I exist, at least that of the main causes, it hasn’t arrived yet.
